Know How Every Agent Is Actually Performing, Human and AI
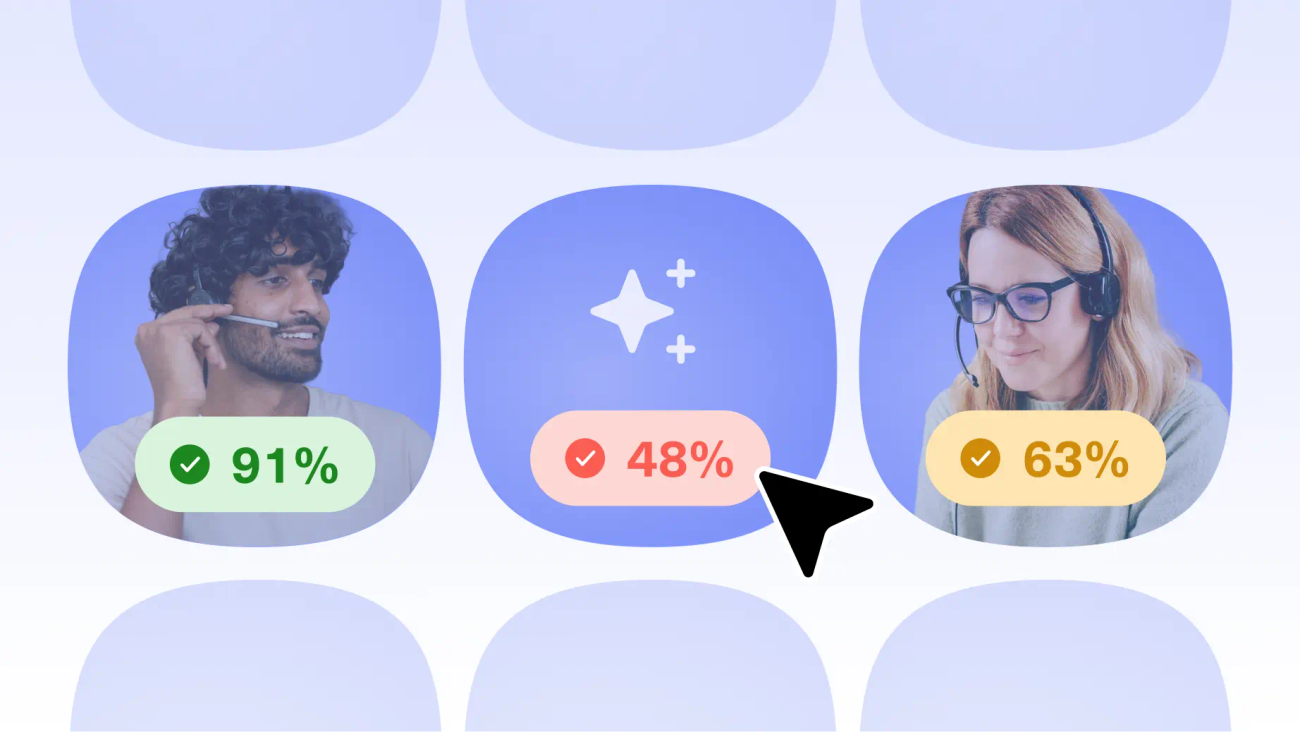
Most QA programs run on a sample, because reading conversations individually doesn't scale. Some teams review as few as one or two conversations per agent per week, out of the hundreds each agent handles, and that tiny sample still feeds directly into performance reviews. Multi-agent conversations often get collapsed into one blended score keyed to whoever handled it last, so credit and blame land on the wrong person. And many companies don't have a formal QA program at all, which means issues usually surface only after you have unhappy customers, not before.
AI agents made this harder, not easier. Now there's a second population of agents handling conversations with no practical way to check their work at scale either.
Introducing AI QA
AI QA is Kustomer's automated quality evaluation engine. It scores every AI agent conversation and every human rep conversation against a weighted scorecard you define, automatically, with the AI's reasoning shown alongside every score. Instead of reviewing a sample and hoping it's representative, you get insights on all of your conversations, for AI agents and human reps alike, built right into the platform you already use.
Think of it like coaching a new hire. You wouldn't hire someone and never check their work. AI QA adds scale because it reviews every conversation instead of a handful, and it never calls in sick.
How it works
One weighted scorecard. You define the criteria that matter to your team, in plain language, no rubric-building tool required, and assign a weight to each one. That same scorecard scores every conversation, AI agent and human rep alike, so it's clear how much any single criterion moves the overall number, and there's no separate rubric to maintain for each.
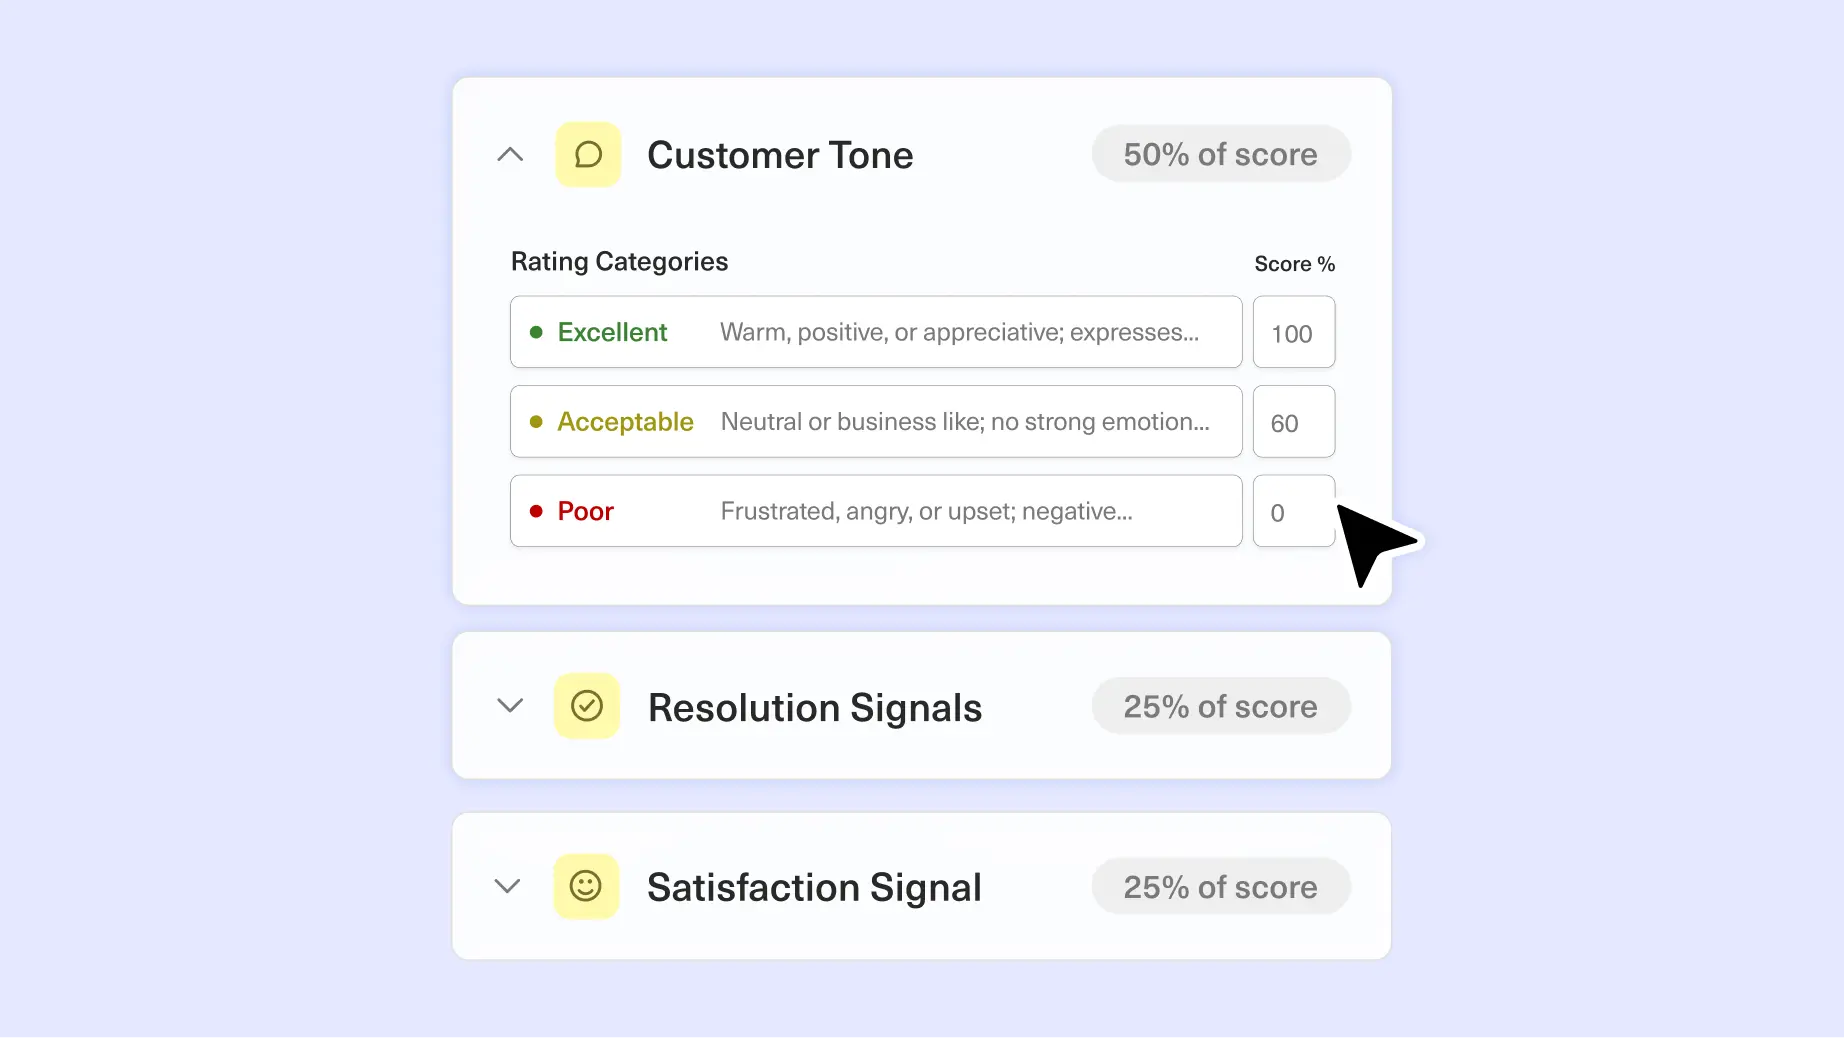
Clear reasoning on every score. Each score comes with the AI's reasoning attached, in plain language, right next to the result. A QA score with no explanation is just a number you either believe or you don't. A QA score with reasoning is something a manager can actually read, evaluate, and act on.
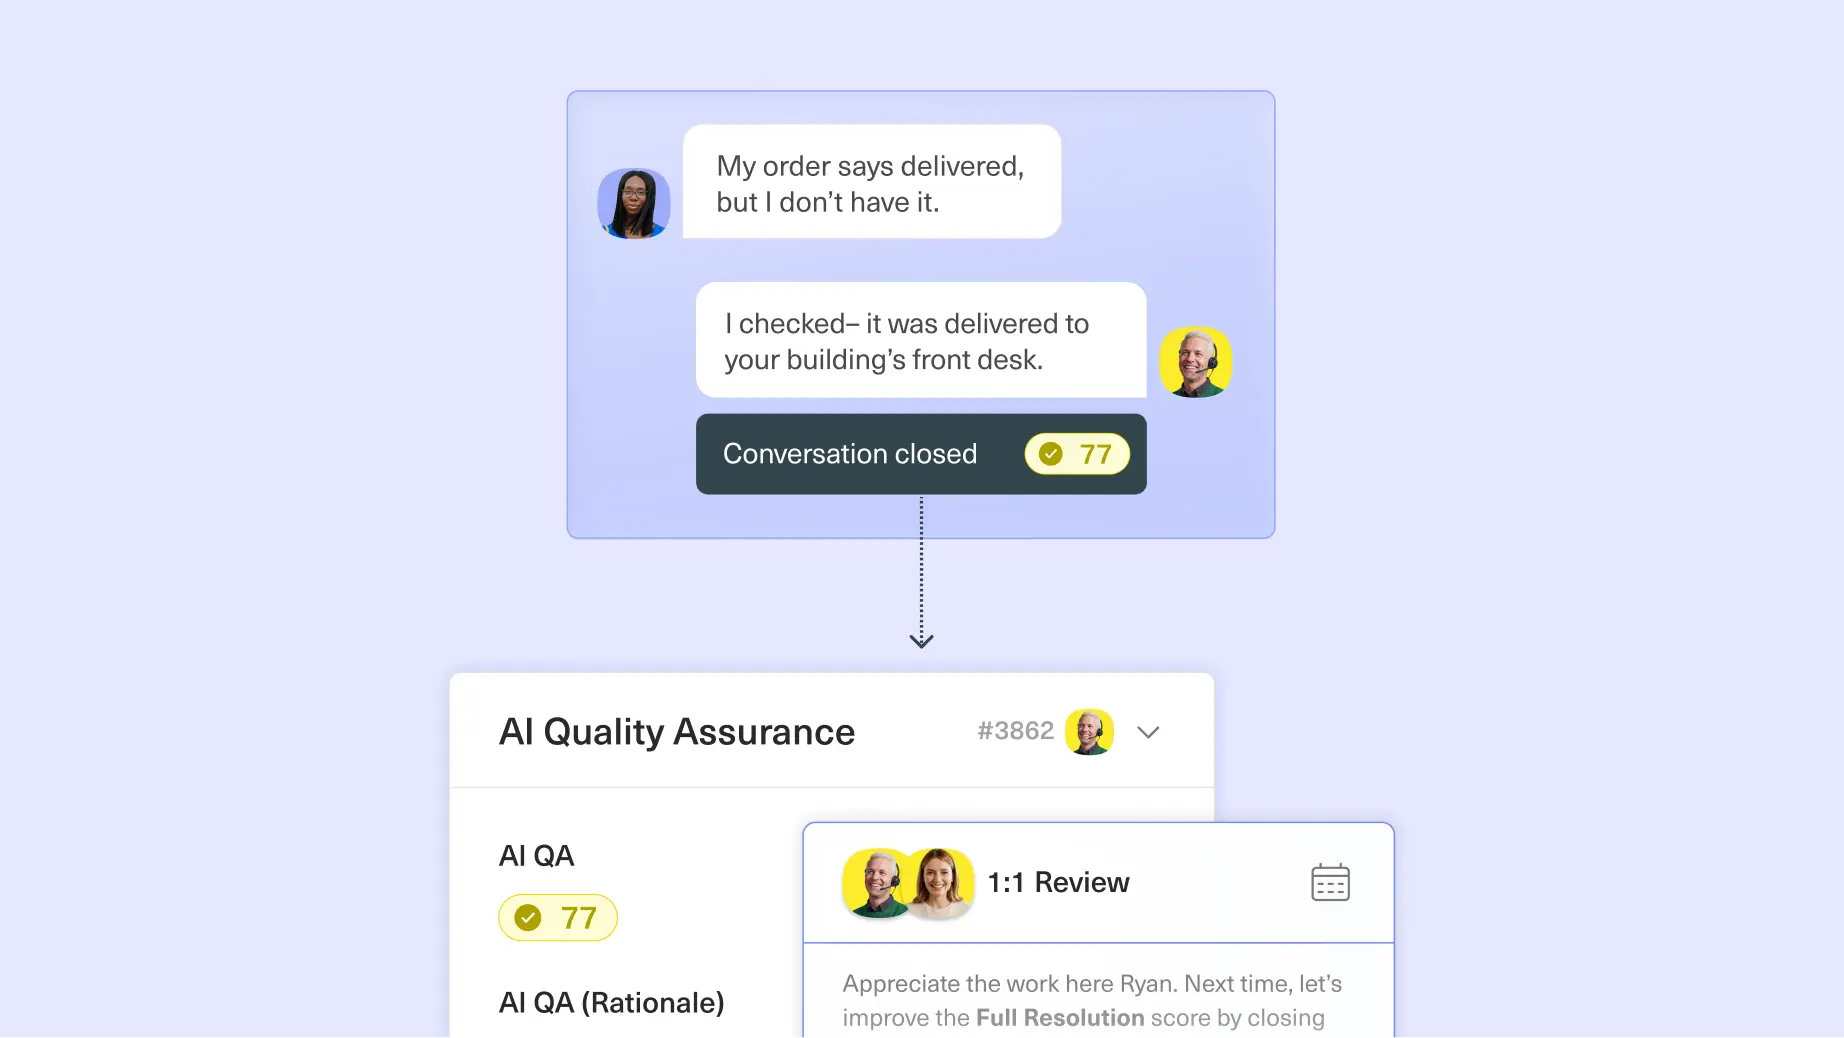
Coaching loops, not a dashboard you have to remember to check. Because the score behaves like any other data on the conversation, it flows straight into reporting and Data Explorer. A manager can ask a plain-language question like "show me coaching opportunities for this rep" and get an answer built on the rep's full scoring history and reasoning, not a hand-picked sample. The same reporting surface makes it easy to pull a straight read on how any rep, team, or AI agent is scoring over time, no custom report required.
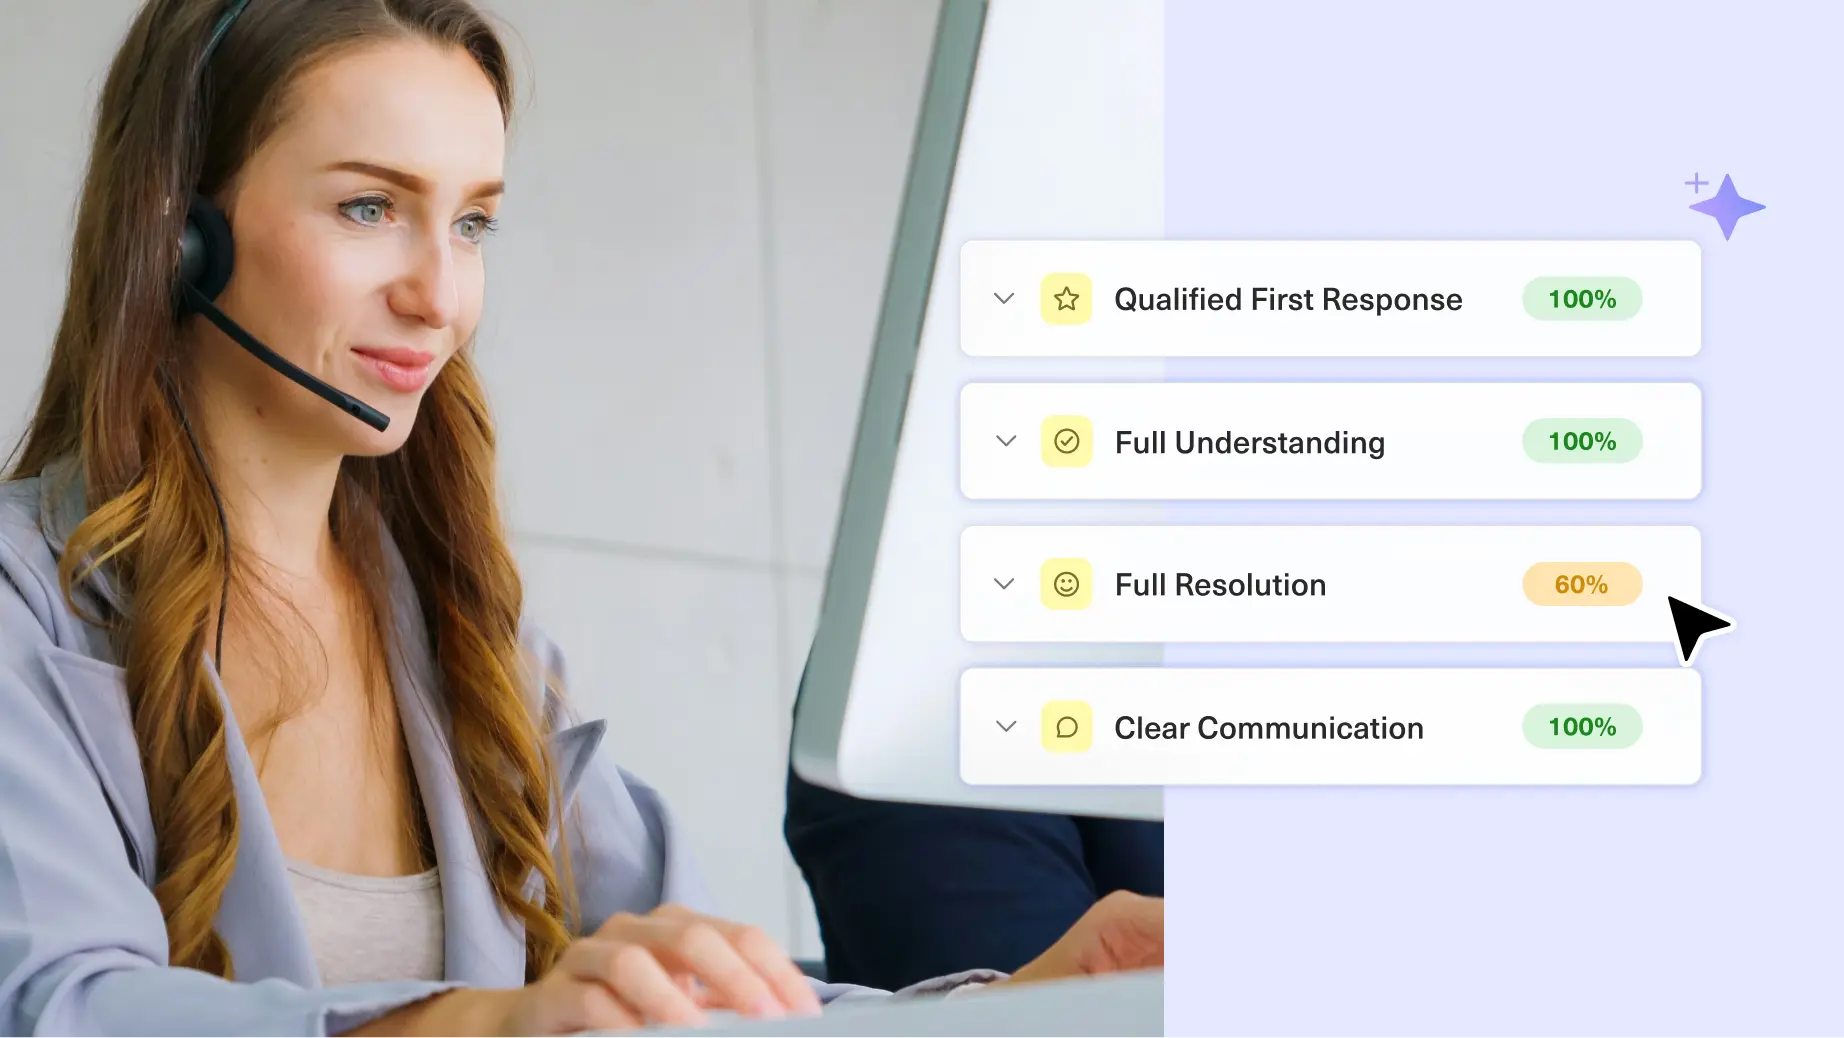
Surface what needs attention, not just what happened. Because every score and its reasoning live on the conversation, you can filter reporting or Data Explorer for the lowest-scoring conversations, human or AI-handled, and go straight to them instead of reading through everything to find the ones that matter. When an AI agent conversation comes back low, the reasoning attached to the score shows exactly what happened, giving the admin what they need to fix the instructions and close the gap.
Built natively, not synced in. AI QA lives where your conversations already live. There's no second login, no separate data model, and no export job to keep two systems in sync.
What this looks like in practice
An AI agent handling a conversation end-to-end. After the conversation closes, AI QA scores it against your criteria. Because the score is a normal attribute on the conversation, you can set up a workflow to automatically flag a low score straight to an admin the moment it happens, rather than waiting for someone to go looking for it. When it comes back low, say the agent skipped confirming a resolution timeline, the reasoning attached to the score shows exactly where it broke procedure, so the admin can update the instructions before it happens again.
A human rep handling a conversation on their own. The rep gets scored against the same rubric and gets credit for what they did well, with reasoning attached, so a manager can see exactly where they excelled and where there's room to grow. When a conversation scores exceptionally high, you can set up a workflow to automatically flag it for the manager, so standout conversations become training examples and recognition moments instead of getting lost in the queue.
An AI agent and a human rep on the same conversation. When an AI agent hands off to a person mid-conversation, say for a manual refund, AI QA doesn't lose the thread. It scores the full conversation as one story, with reasoning that captures how the handoff played out end to end, so a manager sees the complete picture instead of two disconnected snapshots.
Turn It On, Not Set It Up
You don't need to build a scorecard from scratch or bring in engineering to turn AI QA on. A ready-made AI QA field comes preconfigured and turns on in a single click, and you can edit it afterward to match how your team actually evaluates quality.
From there, setup is a matter of writing your criteria in plain language, no rubric-building tool or code required, and choosing when it runs. Once it's live, every closed conversation gets scored automatically, and if a score needs a human correction, you can override it by hand. Once corrected, that value won't be silently overwritten the next time the field runs.
More Than a Score
Support leaders care about impact, cost, and clarity. AI QA gives them the data to show all three: full visibility into how the team, human and AI, is actually performing, not a guess extrapolated from a handful of conversations. QA and coaching managers get consistency at scale, so reviews come from a complete picture instead of a coin flip about which conversations happened to get read. And reps get transparent, fair feedback they can actually act on, because the reasoning behind their score is right there next to it.
None of this replaces human judgment. AI QA doesn't make the call on anyone's performance review. It gives the people making that call a complete picture to work from instead of a partial one.
Get started
New to Kustomer? Book a demo to see AI QA scoring real conversations in your own environment.
Already a Kustomer customer? Reach out to your Customer Success Manager to learn how AI QA fits into your current setup and rollout timeline.